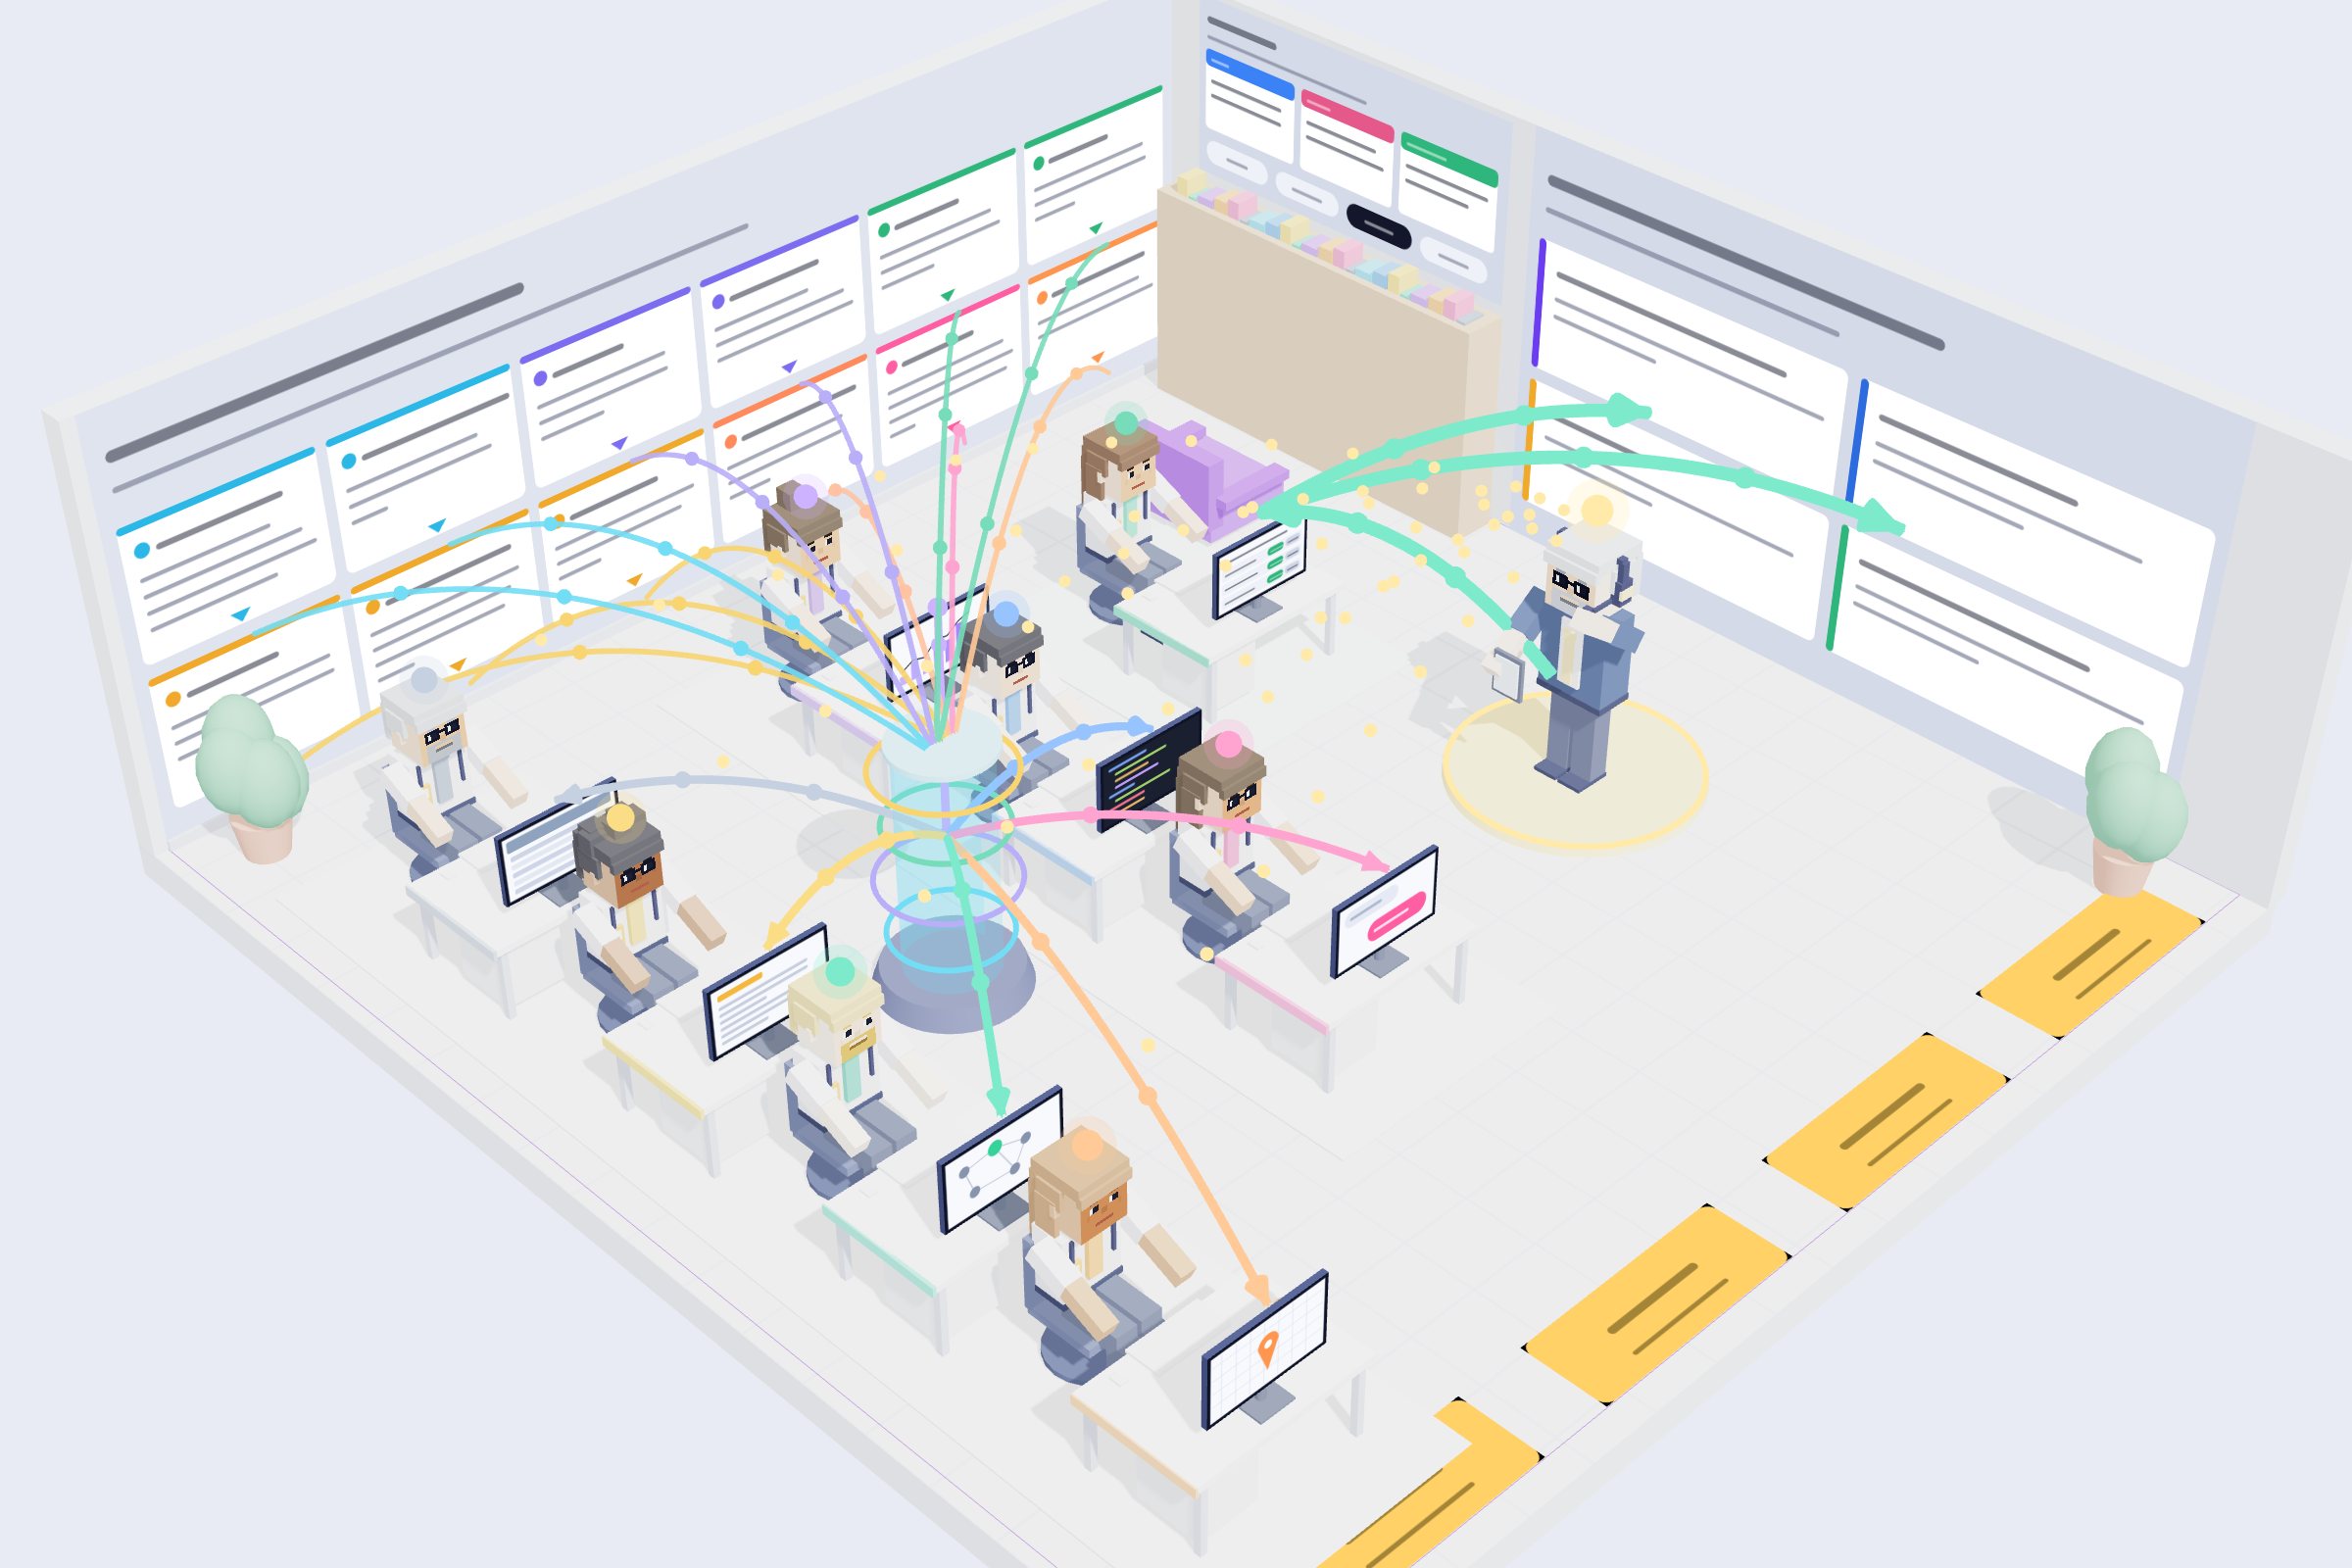
A factory needs light because people need to see what they are doing. Software does not. That is where the term “dark factory” comes from: work that keeps running in the background, even when nobody triggers every step by hand. For a company today this does not mean that nobody works any more. It means that knowledge, data and recurring tasks come together in a system of your own, on which AI agents can work reliably.
Local AI for companies, in short
Local AI means that a language model runs on your own computer or server instead of at a cloud provider. Your data stays in the house. For the AI to answer from your knowledge instead of just chatting, it needs a knowledge center behind it: a graph database (we use Neo4j) for relationships, a vector database (Qdrant) for searching by meaning, and rules that tie every answer to a source.
- The knowledge belongs to you and lives on your server. The AI models can be swapped.
- Neo4j stores things and their relationships as nodes and edges, with the date from which something is valid.
- Qdrant finds matching passages by meaning, not only by keyword.
- Every answer names its source. If the system finds nothing, it says so.
- Routine work runs on local models, difficult analysis goes to an external API when needed.
This article is part of our research and development, supported by FFG Project Start. Further down you can click through the setup step by step.
How the AI knowledge center works
Six stages, from the source to the answer. Click a building block to read what happens there.
Shop and inventory system
Products, variants, prices, stock levels, orders and returns, for example from Shopify, a product information system (PIM) or the inventory system. What matters is one source per piece of information: what is maintained in the PIM is not maintained a second time in the knowledge center.
Google Ads, Search Console, Analytics
Campaigns, search terms, clicks, conversions and rankings arrive daily through the official APIs. Search Console delivers data with a two to three day delay; the system knows this and only compares complete days.
Communication with customers and in the team
Emails, chat messages and meeting notes contain decisions and wishes that are written down nowhere else: “keep defending brand terms”, “do not advertise these products”. Such instructions are stored as standing rules per client. What is ingested is a deliberate decision and has to be checked against data protection law.
Documents and manuals
User manuals, warranty terms, FAQs, contracts and offers. They are split into sections so that an answer can name exactly the page where something is written, for example a device error code and what to do about it.
Development work becomes knowledge too
We develop with AI assistants in the terminal, such as Claude Code. Every session contains decisions, mistakes and solutions. These sessions are split into individual steps, cleaned of passwords and keys, and stored as nodes in the graph. That way the system later knows how a similar problem was solved before, and the data can train a local model on our own way of working.
One connector per source
Every source has its own connector that fetches changes: by webhook when the source sends notice, or by polling at fixed intervals. A connector never writes to the database directly. It only reports an event, such as “order received” or “manual updated”.
A queue that loses nothing
All events run through an event stream (in our case Redis Streams), separated per client. Every event carries the time it happened, not when it was processed. If a processing step fails, the event stays and is retried later.
Clean, split, classify
Before anything is stored, credentials and unnecessary personal data are removed, texts are split into sections, and people, products, projects and terms are recognised. A local model does this routine work, so it never leaves the server.
Neo4j stores relationships
Every thing becomes a node (product, manual, customer, campaign, decision), every relationship an edge (“belongs to”, “mentions”, “replaces”). That lets the system answer questions that span several steps: which manual belongs to this device, which warranty applies, which questions have already come up about it?
Qdrant searches by meaning
Every text section is converted into a vector, a series of numbers that describes its meaning. Qdrant then finds sections that match the question, even when different words are used: “device does not cool” also finds “cooling performance decreases”. Every vector carries the client’s ID, and search only covers that client’s data.
Nothing is overwritten
Every relationship has a “valid from” and a “valid until”. When a price, a warranty or a contact person changes, the old relationship is closed and a new one created, not overwritten. That way the system can say what applies today and still explain what applied in March.
No source, no answer
The model only receives the passages and facts that were found, with the instruction to answer from them alone and to name the source. If the material is not enough, the correct answer is “I found nothing on this”, not a guess.
Standing rules every answer knows
Every client has standing rules that are passed along with every request: target markets, budget limits, products that are not advertised, tone of voice. A suggestion has to be measured against these rules and say why it complies.
A person approves
Replies to customers, social media posts and budget changes are stored as drafts. A person reviews and approves, and only then does anything go out. Every approval, edit or rejection is stored and improves the next suggestions.
Local: for routine and confidential work
Our server currently runs two open models through Ollama: Gemma 4 (12B) for text and classification, gpt-oss (20B) for tasks that use tools. They run without a graphics card, one request after another. Nothing is rejected because the machine is busy: requests wait in a queue.
API: for difficult analysis
For strategy, long analyses and good writing we use strong models through an API, such as Claude. They only receive the passages the task needs, not the whole database. Which model it is can be changed at any time, because the knowledge does not live inside the model.
Which task goes where
For each task it is fixed which model gets it: confidential data and bulk work locally, difficult individual cases through the API. Cost, response time and error rate are measured per task, so the split is based on numbers, not on gut feeling.
Agents with a clear role
An SEO agent, a Google Ads agent, a service agent: each with its own role, its own sources and limits. At our company, for example, one agent checks the Google Ads accounts every night and presents suggestions in the morning, another compares prices with large marketplaces.
A chat that looks things up instead of guessing
The chat on the website is just one application of the same knowledge. When someone asks about a device, it answers from product data, the manual and the warranty terms and links to the passage. The same base helps the service team reply and new staff get up to speed.
Figures from the database, text from the model
A report is made in two steps: first the system fetches the figures from the database, then a model writes the text around them, from these figures only. No figure comes from the model’s memory, and every one can be checked.
The knowledge inside Claude Code and Cursor
Through the Model Context Protocol (MCP), AI tools such as Claude Code or Cursor can search the knowledge center directly, with the same permissions and the same separation per client. Anyone working in the terminal has the project’s context at hand without explaining it again every time.

A private AI knowledge center instead of separate chat projects
Many companies start with ChatGPT, Claude or Gemini. That makes sense, but it is not an AI infrastructure of your own. A chat project has limits: how much text fits in at once, what a plan costs, which data you may upload, and the fact that the knowledge sits in a tool that may work differently or cost more tomorrow.
The knowledge center turns this around. The knowledge sits in a database of your own on a server you control. The models access it and can be swapped: Claude today, another model tomorrow, a local one for confidential tasks. If the provider changes, the knowledge stays.
What “self-sufficient” means in practice
- Your server: in your building, in a data center in the EU or at a host of your choice. Not at a chat provider.
- Your data: you can export everything at any time. Neo4j and Qdrant are open software, the data is stored in open formats.
- Your sources: the knowledge center reads from your systems (shop, product information system, inventory system) and maintains nothing twice.
- Your partner can be replaced, us included: the setup is documented, another team can take it over.
Why context is not solved in the chat window
A common misunderstanding is that an AI project automatically knows the whole company. The more data there is, the less fits in, and the more every question costs, because everything is sent along every time. A knowledge center sends the model only the ten passages that match the question. That is faster, cheaper and more accurate.
What is a graph database?
A graph database stores data as nodes and edges. A node is a thing (a product, a person, a document), an edge is the relationship between two things (“belongs to”, “bought”, “is mentioned in”). Both can carry properties, such as a name or a date. Unlike with tables, relationships do not have to be put together again for every query: they are stored and can be followed directly.
This is exactly how company knowledge is structured. A fridge has a manual, the manual describes error codes, a customer asked about one of them, an employee wrote the answer, and the warranty has applied since a certain date. In tables that is five tables and many joins. In a graph it is one path from node to node.
What is Neo4j?
Neo4j is the best-known graph database. It has been on the market since 2007, is developed by Neo4j, Inc. and is queried with the Cypher language, whose ideas went into the ISO standard GQL. There is a free Community Edition (open source), a paid Enterprise Edition and a hosted version called AuraDB. So you can run Neo4j on your own server.
A query reads almost like a sentence. This one finds the valid manual for a product and the questions customers have already asked about it:
MATCH (p:Product {sku: $sku})-[:HAS_MANUAL]->(m:Document)
WHERE p.tenantId = $tenantId
OPTIONAL MATCH (q:Question)-[:ABOUT]->(p)
RETURN p.name, m.title, m.url, collect(q.text) AS questions
What we use Neo4j for
- Relationships across several steps: product, manual, warranty, question, answer. Or: campaign, search term, landing page, conversion.
- Time: every edge has “valid from” and “valid until”. Old relationships are closed, not deleted. That keeps it traceable what applied when.
- Separation per client: every query has to contain the client’s ID, otherwise our software refuses it. Data of two clients cannot mix.
- Agents as data: the AI agents themselves, their instructions, assignments and every single run with input, result and cost are nodes too. You can teach an agent something without shipping new software, and later check what it did and when.
Storing everything as nodes, including the work in the terminal
A knowledge center becomes valuable when it knows not only documents but also work. We therefore store three kinds of nodes: episodes (the raw material, such as an email, meeting notes or a step of a coding session), entities (what appears in them: people, products, projects, terms) and communities (groups of entities that often appear together).
This also applies to our own development work. When we work with an AI assistant in the terminal, a log full of decisions is created: what was tried, what failed, what worked in the end. These logs are cleaned of passwords and keys on our machine, checked a second time on the server and stored as episodes. The result is a memory that helps with the next similar problem, and a training set for a local model that knows how we work.
What is a vector database?
A vector database searches by meaning instead of by exact words. For this, every text section is converted by a so-called embedding model into a vector, a long series of numbers. Texts with similar meaning get similar numbers. When a question comes in, it is converted too, and the database returns the sections with the most similar numbers. That way “device no longer cools properly” also finds the manual section “cooling performance decreases”.
What is Qdrant?
Qdrant is an open-source vector database, written in Rust and free to use under the Apache 2.0 license. It runs on your own server or as a hosted service. Two things matter for companies: Qdrant can combine every search with filters (only this client’s data, only valid documents, only this language), and it can combine search by meaning with keyword search. Item numbers and error codes are found as reliably as paraphrased questions.
In our setup every vector carries the client’s ID, and every search filters by it. The conversion into vectors is currently done by an external embedding model. For confidential data this can also run fully locally, for example with bge-m3 or Qwen3-Embedding, both available through Ollama.
Graph or vector? Both.
| Question | Graph (Neo4j) | Vector (Qdrant) |
|---|---|---|
| What is connected to this? | Strong: follows relationships across several steps | Weak: knows no relationships |
| Where is something similar written? | Weak: needs exact terms | Strong: finds paraphrases |
| What applied in March? | Strong: edges with “valid from/until” | Only through filters on date fields |
| Figures, totals, lists | Strong: exact queries | Not suitable |
The graph says what belongs together and what applies. The vector search finds the right passage in the text. Together they give the model exactly the material it needs for a good answer.
RAG: how the AI answers from your data
RAG stands for retrieval-augmented generation: answering after searching first. The model does not answer from memory; it first receives the matching passages from your data. A RAG system has three steps:
- Retrieve: vector search and graph find the passages and facts for the question.
- Assemble: only these passages are passed to the model, with their source, plus the client’s rules.
- Answer: the model writes the answer from this material and names the source.
Is ChatGPT a RAG system? Only when it searches the web or uploaded files. The difference with a RAG system of your own: you decide which sources exist, who may see what, and that every answer is backed by a source.
GraphRAG: search that knows relationships
Pure vector search finds similar passages but misses relationships that are not written in any single sentence. With GraphRAG the system also follows the edges in the graph: it finds the manual section and knows from the graph which model it applies to, which warranty goes with it and that there has been a successor since May. That is why we run both.
New context every day: how external knowledge comes in
A knowledge center is only as good as its latest state. That is why intake runs continuously, not once:
- Immediately: sources that can send notice (shop orders, forms, chat messages) report changes by webhook, usually within seconds.
- Several times a day: sources without notifications (project management, document storage) are polled at fixed intervals.
- Nightly: ad accounts, Search Console and Analytics are fetched for the previous day and compared. After that the agents run that turn this into suggestions for the morning.
- From outside when needed: marketplace prices, holidays and promotion days, new laws or platform rules are queried on purpose and stored with source and date.
Every new piece of information gets the time it came into being. If it contradicts an old one, the old one is not deleted but closed with “valid until”. That way the system sees the next morning what has changed, and can explain it.
Avoiding AI hallucinations: seven rules
A hallucination is an answer that sounds convincing but is not true. With language models it cannot be ruled out completely; anyone who promises that is promising too much. But it can be made rare and, more importantly, recognisable. These are the rules we apply:
- Answers only from material that was found. The model receives the matching passages and the instruction to answer from them only.
- Every answer names its source. A link to the manual, the email or the record. No source, no claim.
- “Not found” is an allowed answer. The system should rather admit that it does not know than guess.
- Figures come from the database, never from the model. First the figures are queried, then the model writes the text around them. Every figure can be checked.
- Fixed formats instead of free text. Where an answer is processed further, the model has to return a fixed format that the software checks. If it does not fit, it is discarded instead of guessed.
- Only valid knowledge. Thanks to the timeline in the graph, the model sees the current price, not last year’s.
- A person approves, and every answer is logged. A person checks what goes out. Every request is recorded with input, output and cost, and errors are counted. If the error rate rises, the system pauses the affected task.
Local AI: which models make sense today
A local LLM is a language model whose weights you download and run on your own hardware. Since 2025, open models have become good enough to handle many everyday company tasks reliably: classifying, summarising, extracting data from text, writing drafts, working with tools. For difficult analysis, the large models of the providers stay ahead.
Ollama, LM Studio or vLLM?
- Ollama: the simplest way on a server or a Mac. One command downloads a model, an API makes it available to other software. We use Ollama.
- LM Studio: a desktop app with a user interface, good for trying things out on your own computer.
- vLLM: for servers with graphics cards, when many requests have to be answered at the same time.
Three rules of thumb for the hardware
- Memory decides, not the processor. A model has to fit completely into RAM (or the graphics card’s memory). Count the model’s file size plus 2 to 4 GB for context and the system.
- Quantised is the normal case. Models are usually loaded with 4 bits per weight instead of 16. That saves three quarters of the memory and costs little quality. “QAT” variants are prepared for this during training and lose even less.
- Apple Silicon and graphics cards are fast, plain CPU is slow. A Mac with a lot of unified memory or a PC with a strong graphics card answers in seconds. Without a graphics card it still works, but rather for tasks that may run in the background. That is exactly how our own server runs.
The overview below lists models available in the Ollama library in October 2026, with their download size in the 4-bit variant. Choose your computer’s memory size.
Which local AI fits which computer
As of 23 October 2026. For each memory size the strongest open models, split into text, code, images and video. Sizes are download sizes of the named variant (mostly 4-bit). On a Mac the graphics unit only gets about two thirds to three quarters of the memory by default; that is taken into account.
16 GB: the entry level
One model at a time, for routine work in the background. Not enough for video.
| Use | Model | Size | What for |
|---|---|---|---|
| Text | gemma4:12b-it-qat | 7.2 GB | best all-rounder for 16 GB (runs at our company) |
| Text | qwen3.5:9b | 6.6–7.6 GB | fast, understands images too |
| Code | qwen3.5:9b | 6.6–7.6 GB | small coding help, no agents |
| Images | FLUX.2 [klein] 4B | ≈ 8 GB | fast images, Apache 2.0 |
| Images | Z-Image-Turbo 6B | ≈ 12 GB | photo look in 8 steps, Apache 2.0 |
| Search (embeddings) | bge-m3 | 1.2 GB | vector search, multilingual |
Suitable hardware: MacBook Air or Mac mini with 16 GB, or a small server.
32 GB: the sensible standard
From here a model answers customer questions from the knowledge center well, works with tools and writes decent code.
| Use | Model | Size | What for |
|---|---|---|---|
| Text | qwen3.8:27b | 18 GB | strongest model in this class, long context |
| Text | gemma4:31b-it-qat | 19 GB | very good German |
| Text | gpt-oss:20b | 14 GB | tools and agents (runs at our company) |
| Code | devstral-small-2:24b | 15 GB | coding agent, SWE-bench Verified 65.8% |
| Code | qwen3.6:35b | 23–24 GB | fast (only 3B parameters active) |
| Images | Qwen-Image-2512 (Q4–Q5) | 12–15 GB | best text in images, Apache 2.0 |
| Images | FLUX 3 Image Klein | 11 GB | newest FLUX, editing too (revenue limit) |
| Video | Wan 2.2 TI2V-5B | ≈ 10 GB | 720p, 5 seconds, Apache 2.0; slow on a Mac |
Suitable hardware: A Mac with 32 GB, or a PC with a graphics card of 24 GB or more.
64 GB: several models at once
Several models stay loaded, long documents fit into the context, images in full quality.
| Use | Model | Size | What for |
|---|---|---|---|
| Text | qwen3.8:27b (Q8) | ≈ 31 GB | full quality of the 27B model |
| Text | gemma4 + gpt-oss + bge-m3 | ≈ 23 GB | text, tool and search model together (our setup) |
| Code | qwen3-coder-next | 52 GB | best coding model for 64 GB, tight |
| Images | Qwen-Image-2512 (BF16) | 41 GB | full quality, Apache 2.0 |
| Video | LTX-2.5 (Q8) | 23 GB | video with sound (revenue limit) |
| Video | Wan 2.2 A14B (GGUF) | 15–30 GB | best open motion quality, Apache 2.0; very slow on a Mac |
Suitable hardware: Mac Studio or Mac mini with 64 GB, or a server with 64 GB of RAM and a graphics card.
128 GB: large open models
The large open models run in-house. For many tasks they come close to the large providers’ models.
| Use | Model | Size | What for |
|---|---|---|---|
| Text | gpt-oss:120b | 65 GB | fast, good reasoning, Apache 2.0 |
| Text | qwen3.5:122b | 81 GB | strong all-rounder with image understanding |
| Code | qwen3-coder-next (Q8) | 85 GB | coding without quality loss |
| Code | devstral-2:123b | 75 GB | SWE-bench Verified 72.2% (licence excludes very large companies) |
| Images | Qwen-Image-2512 + Edit-2511 | je 41 GB | generate and edit, Apache 2.0 |
| Video | LTX-2.5 (BF16) | 42 GB | full quality with sound (revenue limit) |
| Video | Wan 2.2 A14B (BF16) | ≈ 60 GB | best Apache video option |
Suitable hardware: Mac Studio M5 Max with 128 GB, NVIDIA DGX Spark, or a PC with AMD Ryzen AI Max+ 395 (128 GB).
256 GB: top models in-house
Models with 300 to 400 billion parameters run here, of which only a small part works per word (mixture of experts). They are mostly not in the Ollama library but run as GGUF files through llama.cpp or LM Studio.
| Use | Model | Size | What for |
|---|---|---|---|
| Text | DeepSeek-V4-Flash (284B, 13B aktiv) | 155–162 GB | 1M token context, MIT; about 35 tokens/s on an M3 Ultra (MacStories) |
| Text | Qwen3.5-397B-A17B (IQ4_XS) | 190 GB | Qwen’s open flagship, Apache 2.0 |
| Code | GLM-5.3-Flash (320B, 18B aktiv) | 157–200 GB | strong coding and agent model, MIT |
| Code | Qwen3.8-Flash-Next (Q8) | 189 GB | coding agent at full precision (Qwen community licence) |
| Images | Qwen-Image, LTX-2.5, Wan 2.2 | 41–64 GB | as with 128 GB: more memory hardly helps images and video, graphics power counts |
Suitable hardware: Mac Studio M5 Ultra with 256 GB, or two linked NVIDIA DGX Spark.
512 GB: the maximum on one machine
The largest open models that still fit on a single machine, with 675 to 750 billion parameters. Slower than in the cloud, but fully in-house.
| Use | Model | Size | What for |
|---|---|---|---|
| Text | Mistral Large 3 (675B, 41B aktiv) | 360–388 GB | European provider, Apache 2.0 |
| Text | DeepSeek-V4.1-Flash (Q4) | ≈ 300 GB RAM | newest DeepSeek, part stays on the SSD; MIT |
| Code | GLM-5.3 (744B, 40B aktiv) | 343–365 GB | strongest open coding model that fits on a Mac (own GLM licence) |
| Code | qwen3-coder:480b | 290 GB | older (2025), but straight from Ollama, Apache 2.0 |
Suitable hardware: Mac Studio M5 Ultra with 512 GB.
No longer fits: Kimi K3 (2.8 trillion parameters) and DeepSeek-V4-Pro (1.6 trillion). They need a server with several graphics cards or several linked Macs.
With a graphics card: speed, images and video
An NVIDIA graphics card is much faster than a Mac for images and above all video, as long as the model fits into its own memory (VRAM). For many simultaneous requests vLLM is better than Ollama.
| Use | Model | Size | What for |
|---|---|---|---|
| Text | qwen3.8:27b, gemma4:31b | 18–19 GB | smooth on 24–32 GB of VRAM (RTX 4090/5090) |
| Code | devstral-small-2:24b | 15 GB | coding agent on one card |
| Images | FLUX 3 Image Klein (INT8) | ≈ 6 GB | about 4 seconds per image on an RTX 5090 (vendor) |
| Video | Wan 2.2 TI2V-5B | ≥ 24 GB VRAM | 720p clips in minutes instead of hours |
| Text | gpt-oss:120b | 65 GB | on an RTX PRO 6000 (96 GB) without compromise |
| Video | Wan 2.2 A14B | ≥ 80 GB VRAM | full video quality without offloading |
Suitable hardware: An RTX 4090 or 5090 (24–32 GB) to start, an RTX PRO 6000 (96 GB) as the best single card.
Rent instead of buying: for a test, a rented server with a graphics card in an EU data center is enough, by the hour or by the month.
Speech and search: small models, big value
These models are small and run on almost any computer next to a language model: transcribing meetings, reading texts aloud, preparing documents for search.
| Use | Model | Size | What for |
|---|---|---|---|
| Speech to text | Whisper large-v3-turbo | ≈ 1.6 GB | standard for transcripts, good German, MIT |
| Speech to text | Parakeet TDT 0.6B v3 | ≈ 1.2 GB | 25 EU languages, very fast (CC-BY) |
| Text to speech | Chatterbox Multilingual | ≈ 1 GB | 23 languages incl. German, custom voices, MIT |
| Text to speech | Qwen3-TTS 1.7B | ≈ 3.5 GB | German, voice design, Apache 2.0 |
| Search (embeddings) | qwen3-embedding:8b | 4.7 GB | top for multilingual search, Apache 2.0 |
| Search (embeddings) | bge-m3 | 1.2 GB | proven for RAG, MIT |
Suitable hardware: Any computer with 16 GB or more.
Note: the popular Kokoro has no German voices.
Which hardware for local AI? The market in October 2026
Three routes that work today: Apple with unified memory (quiet, lots of memory, no CUDA), NVIDIA graphics cards (fastest, but little memory per card) and AMD Ryzen AI Max (the cheapest route to 128 GB). Choose a device.
Mac mini: the quiet always-on box
M6 with 16, 24 or 32 GB (153–170 GB/s), M5 Pro with 24, 48 or 64 GB (307 GB/s).
- Good for: a knowledge center in the office, models up to 14B parameters (M6); with M5 Pro and 64 GB even 70B models
- But: 64 GB maximum; Amazon only has the smaller configurations, more memory only from Apple
MacBook: AI to take along
MacBook Air M5 with up to 32 GB; MacBook Pro with M5 Pro (up to 64 GB) or M5 Max (36–128 GB, up to 614 GB/s).
- Good for: AI on the go; the MacBook Pro M5 Max with 128 GB is the only laptop for gpt-oss-120b
- But: the Air has no fan and throttles on long runs; 128 GB only directly from Apple
Mac Studio: the most memory on one desk
M5 Max with 36–128 GB (up to 614 GB/s), M5 Ultra with 96, 256 or 512 GB (1.2 TB/s). According to Apple the 512 GB version arrives in late October.
- Good for: the 256 and 512 GB tiers from the table above: DeepSeek-V4, GLM-5.3, Mistral Large 3 in-house
- But: no CUDA (Metal, MLX, llama.cpp); M5 Ultra only from Apple, Amazon only has the base M5 Max
RTX 5070 Ti and 5080: the affordable CUDA entry
16 GB GDDR7 each (896 or 960 GB/s), 300 or 360 W.
- Good for: images (FLUX, Qwen-Image) and models up to 14B parameters, very fast
- But: 16 GB is tight for language models; needs a PC with a suitable power supply
RTX 5090: the fastest card for home use
32 GB GDDR7 at 1,792 GB/s, 575 W, power supply of 1,000 W or more recommended.
- Good for: models up to about 32B parameters at high speed, video with Wan 2.2, fine-tuning small models
- But: power and noise; on Amazon currently only through marketplace sellers at strongly inflated prices, so no link here
RTX PRO 6000 Blackwell: the best single card
96 GB GDDR7 with ECC, 1,792 GB/s, 600 W.
- Good for: gpt-oss-120b, 70B models at high precision, video without compromise, serious fine-tuning
- But: very high price class; through system integrators rather than Amazon
DGX Spark: CUDA with 128 GB in a small box
Grace Blackwell GB10 chip, 128 GB unified memory (273 GB/s). Also from ASUS, Dell, HP, Lenovo, MSI, Acer and Gigabyte.
- Good for: according to NVIDIA models up to 200B parameters, two linked units up to 400B; CUDA tools as in the data center
- But: memory bandwidth is low, answers come much slower than on an RTX 5090 or an M5 Ultra; Linux on ARM
Ryzen AI Max+ 395: 128 GB at the lowest price
16 cores, Radeon 8060S, up to 128 GB unified memory (about 256 GB/s). For example GMKtec EVO-X2, Minisforum MS-S1 Max, HP Z2 Mini G1a, Framework Desktop.
- Good for: gpt-oss-120b, 70B models and large mixture-of-experts models in the office, without a Mac or an expensive graphics card
- But: bandwidth about a fifth of an M5 Ultra; the software (ROCm, Vulkan) is less mature than CUDA. The successor Ryzen AI Max+ PRO 495 (up to 192 GB) can be pre-ordered, but is not on Amazon yet.
HP Z2 Mini G1a: the same class with business support
Ryzen AI Max+ PRO 395 with up to 128 GB, of which up to 96 GB for graphics.
- Good for: companies that want warranty, remote management and a known manufacturer
- But: Amazon only has the 64 GB configuration, 128 GB through specialist retailers
Local or external API? It depends on the task
The question is not “local or cloud” but: which task needs which model? Choose a task.
Purchase prices, contracts, personnel data
What must not leave the building is handled by a local model. Purchase prices, margins, contracts or applications never have to be sent to a provider, not even encrypted. The quality is usually entirely sufficient for classifying, summarising and comparing.
Thousands of small tasks
Tagging thousands of products, classifying search terms, sorting emails: with an API every request costs money, locally only electricity. At our company a local model classifies the search terms from the ad accounts every night before an agent makes suggestions.
Before anything moves on
Removing personal data, splitting texts, detecting language, finding duplicates. If an external API is still needed afterwards, it only receives what is necessary.
Local draft, difficult cases via API
Most questions repeat: delivery time, warranty, error code. A local model writes the draft from the knowledge center. If a request is unusual or sensitive, it goes to a stronger model. In both cases a person approves.
Facts locally, polish via API
A local model extracts the facts (dimensions, energy class, scope of delivery) from the product data. For category pages or important products where tone and search engines matter, a strong model writes the copy, based on exactly these facts.
Transcript locally, analysis depending on content
The transcript of a conversation is made locally. Whether the summary runs locally or via API depends on what was discussed. Confidential matters stay in-house.
When quality makes the difference
A campaign analysis over three months, a concept, assessing an offer: here the large models are clearly better, and a request usually costs only cents. The model receives the necessary figures and passages, not the database.
For readers who matter
Newsletters, guide articles, translations into several languages: large models clearly do better at tone, style and nuance. The facts still come from the knowledge center.
Development with AI assistants
For software development in the terminal we use the strongest models available. The project’s context comes from the knowledge center through MCP; credentials stay out.
First with the best model, then move it
We test a new task first with a strong model to see what is possible. Once it works reliably, we check whether a local model does it just as well. Often it does, and running costs drop.
GDPR-compliant AI: what matters
Local models solve many data protection questions, because the data stays in the building. Where an external API is used, the same rules apply as for any other service provider:
- A data processing agreement with the provider, and processing in the EU where it is offered.
- No training on your data: this is standard with the business APIs of the large providers, but check it in the contract anyway.
- Send only what is needed: the knowledge center gives the model ten matching passages, not the customer database. Personal data is removed locally beforehand where it is not needed.
- Labelling: anyone talking to a chat assistant should be able to tell that an AI is answering. The EU AI Act requires this too.
- Decide deliberately what goes in: whether emails, chat groups or meeting notes are ingested is a decision to make with your data protection officer, not a technical default.
This does not replace legal advice, but it shows why the architecture helps here: whoever holds their own data can decide for every task where it goes.
What AI agents really mean in such a system
An agent is not simply a chatbot with a name. A well-defined agent has a role, tasks, access to certain sources, clear limits and a feedback system. An SEO agent works differently from a Google Ads agent or a service agent. Because role, instructions and every run are stored in the graph, an agent can be refined at any time, and what it did stays traceable.
Automate, suggest, or deliberately leave alone
Not every task should be automated. Some processes run fully automatically when risk and complexity are low, such as technical checks or classifying data. Others only produce suggestions that a person reviews: budgets, customer communication, content. Others again are too sensitive or not standardised enough. There the system first collects knowledge, and we reassess later.
The realistic path to a dark factory
An autonomous platform is not built overnight. It grows through real use cases, clear data models, secure infrastructure and repeated learning. The path starts with observing and structuring, continues with suggestions and approvals, and for suitable processes can later lead to controlled automation. A good first step is a single task with clear value, such as an assistant that answers product questions from manuals and warranty terms and backs every answer with a source.
Why e-commerce companies benefit in particular
Online retailers have many data sources and many recurring questions: shop, product data, stock, ad accounts, Search Console, Analytics, newsletters, customer service, returns and suppliers. An example: a retailer of household appliances gets the same questions every day about error codes, energy classes and warranty. If product data, manuals and warranty terms are in the knowledge center, the chat assistant answers these questions with a link to the right page, the service team gets ready drafts, and new staff learn from the same answers.
A single AI tool or a private knowledge center?
| Area | Single AI tool | Private knowledge center |
|---|---|---|
| Knowledge storage | Knowledge lives in a tool’s chats or projects | Knowledge lives in your own controlled infrastructure |
| Model dependency | Dependent on one provider and its limits | Different models usable via API or locally |
| Context | Limited by tokens, plans and project logic | Scalable through search, graph and data structure |
| Data sources | Often pasted in by hand or scattered | Sources are connected systematically |
| Agents | Mostly general chat assistants | Agents with a role, tasks and limits |
| Feedback | Stays in the chat history | Improves agents and processes |
| Automation | Individual workflows or prompts | Processes with approvals and checkpoints |
| Security | Depends on the provider’s configuration | Private, local or separated per client |
| Long-term value | Quick productivity | A growing company memory |
Research with FFG Project Start: seven questions we examine
The focus is not on hastily claiming a finished product, but on real testing.
Which data sources really add value?
Not every integration makes sense. We check which sources actually enable better decisions: shop, ad accounts, Search Console, Analytics, CRM, email, service, documents, project management. What counts is the concrete value in day-to-day work.
Which agent roles make sense?
A good agent needs a clear role. An SEO, Google Ads, service, e-commerce or project management agent each has different tasks, sources and limits. The question is not only whether an agent is technically possible, but whether it adds value day to day.
Which tasks can be fully automated?
Tasks that are recurring, low-risk and clearly rule-based: structuring data, simple classification, monitoring, technical checks, internal summaries. Even here you need logging, control and proper error handling.
Where are suggestions better than autopilot?
Many valuable tasks should not be executed automatically right away. AI prepares suggestions, reports, drafts or warnings; people review and approve. Especially for budgets, customer communication, recommendations, content and technical changes.
Which processes should not be automated today?
Some processes are too sensitive, too complex or too dependent on human context. Then it makes more sense to collect knowledge first, observe the process and reassess later, rather than forcing automation.
How does feedback improve the agents?
Was a suggestion accepted, edited or rejected? Which information was missing? Such feedback is stored and over time improves instructions, roles, data models and processes.
How does the system stay independent and secure?
The knowledge layer stays independent of any single model. This includes security concepts for access keys, data access, backups, separation per client and approvals. Without these foundations, AI infrastructure quickly becomes risky.
Frequently asked questions
Neo4j is a graph database: it stores things as nodes and their relationships as edges and is queried with the Cypher language. It is used when relationships matter, for example for knowledge graphs, recommendations, fraud detection or, as in our case, as the memory of AI agents.
The Community Edition is open source and free, including running it on your own server. The Enterprise Edition with features such as clustering is paid, and AuraDB is the hosted version with a free entry tier.
Qdrant is an open-source vector database. It stores texts as vectors and finds passages by meaning, combined with filters and keyword search. It runs on your own server or hosted and is the search engine behind many RAG systems.
A graph database stores what is connected to what and what applied when. A vector database finds similar texts, even when different words are used. An AI knowledge center usually needs both: the graph for relationships, the vectors for search.
RAG stands for retrieval-augmented generation: answering after searching first. Before answering, the language model receives matching passages from your own data and answers from them instead of from its general knowledge.
With 16 GB, models up to about 12 billion parameters run well, such as Gemma 4 12B. With 32 GB, Qwen 3.8 27B and gpt-oss 20B are added; with 64 GB several models at once and Qwen3-Coder-Next for code; with 128 GB gpt-oss 120B. From 256 GB top models such as DeepSeek-V4-Flash run, with 512 GB GLM-5.3 and Mistral Large 3. As of October 2026.
No, but you can make them rare and recognisable: answers only from material that was found, every answer with a source, “not found” as an allowed answer, figures straight from the database, and a human approval before anything goes out.
Partly. For recurring and structuring tasks local models are very well suited, especially when data protection or cost matter. For strategy, high-quality writing and demanding analysis external models are still stronger. The combination is usually best.
The term comes from manufacturing: a factory where machines work without people needs no light. In the digital sense it describes a structure in which data, agents and checkpoints work together and routine keeps running in the background. People still decide where it matters.
We would be careful. Individual processes can already be automated very well or supported by AI. A fully autonomous company is much more complex, because data quality, accountability, security, law and human judgement play a large role. The realistic path is step-by-step testing instead of big promises.
AI is very strong at analysis, structure and suggestions, yet mistakes, wrong priorities or missing context still happen. For budgets, customer communication, legal topics, technical changes and sensitive data a person should review and decide. Good AI infrastructure does not replace control, it makes it more efficient.
The future of AI in a company does not lie in solving everything in one chat window, but in a secure, structured knowledge system of your own that can work with different models. Some tasks get automated, some prepared as suggestions, some deliberately stay with people. That distinction is the realistic path.
Looking for an AI software agency? We build AI software and AI agents for SMEs. More about our technology stack. For sales and service: AI agents for sales and customer service.